-
Git — Version Control with SourceTree
SourceTree is a free Git GUI client by Atlassian that lets you visualise and drive the full Git workflow without the command line. This guide walks through the complete feature branch cycle a developer follows when working in a team — from pulling the latest main to cleaning up after a merge.
1. Create a New Branch
Before starting any work, make sure your local
mainis up to date, then create a dedicated branch for your feature.Pull main
Open SourceTree. Make sure you are on the main branch (click it in the left sidebar under Branches). Click the Pull button in the toolbar to fetch and merge the latest remote changes. This ensures your new branch starts from the most recent state of the project, avoiding conflicts later.
Create a new branch
Click the Branch button in the toolbar (or right-click main in the sidebar → Branch…).
Enter a descriptive name following your team’s convention:
feature/my-feature-with-a-descriptive-name
bugfix/null-pointer-on-login
hotfix/payment-timeout
A good branch name tells your teammates what the work is about before they open a single file. Make sure Checkout New Branch is checked, then confirm.
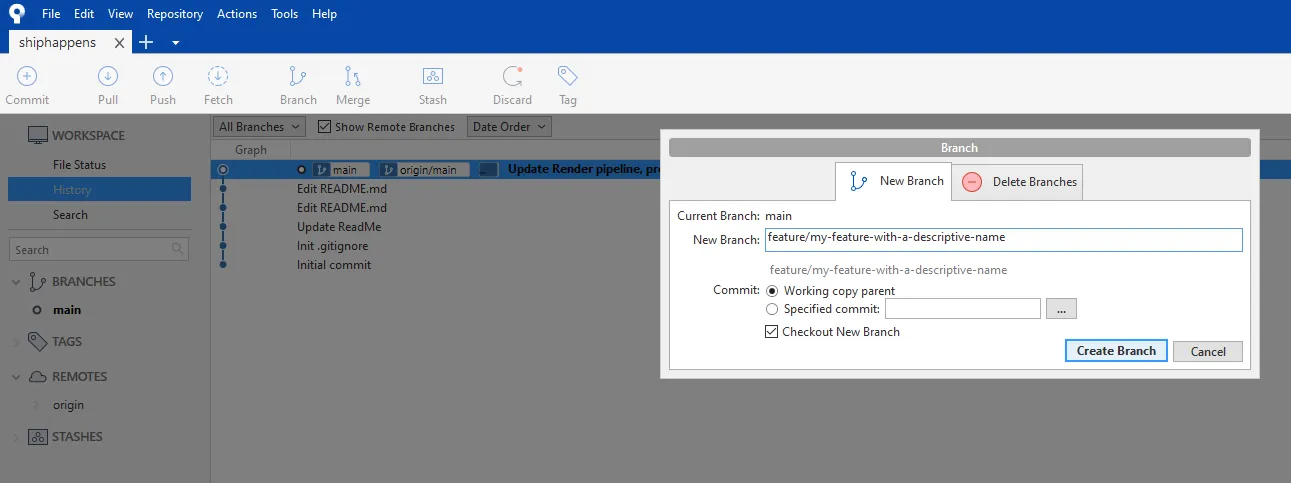
You are now on your feature branch. Any commits you make will stay isolated from
mainuntil you open a Merge Request.
2. Commit and Push Your Changes
Work on your feature. When you are ready to save a snapshot, switch to the File Status tab in SourceTree.
Stage your changes
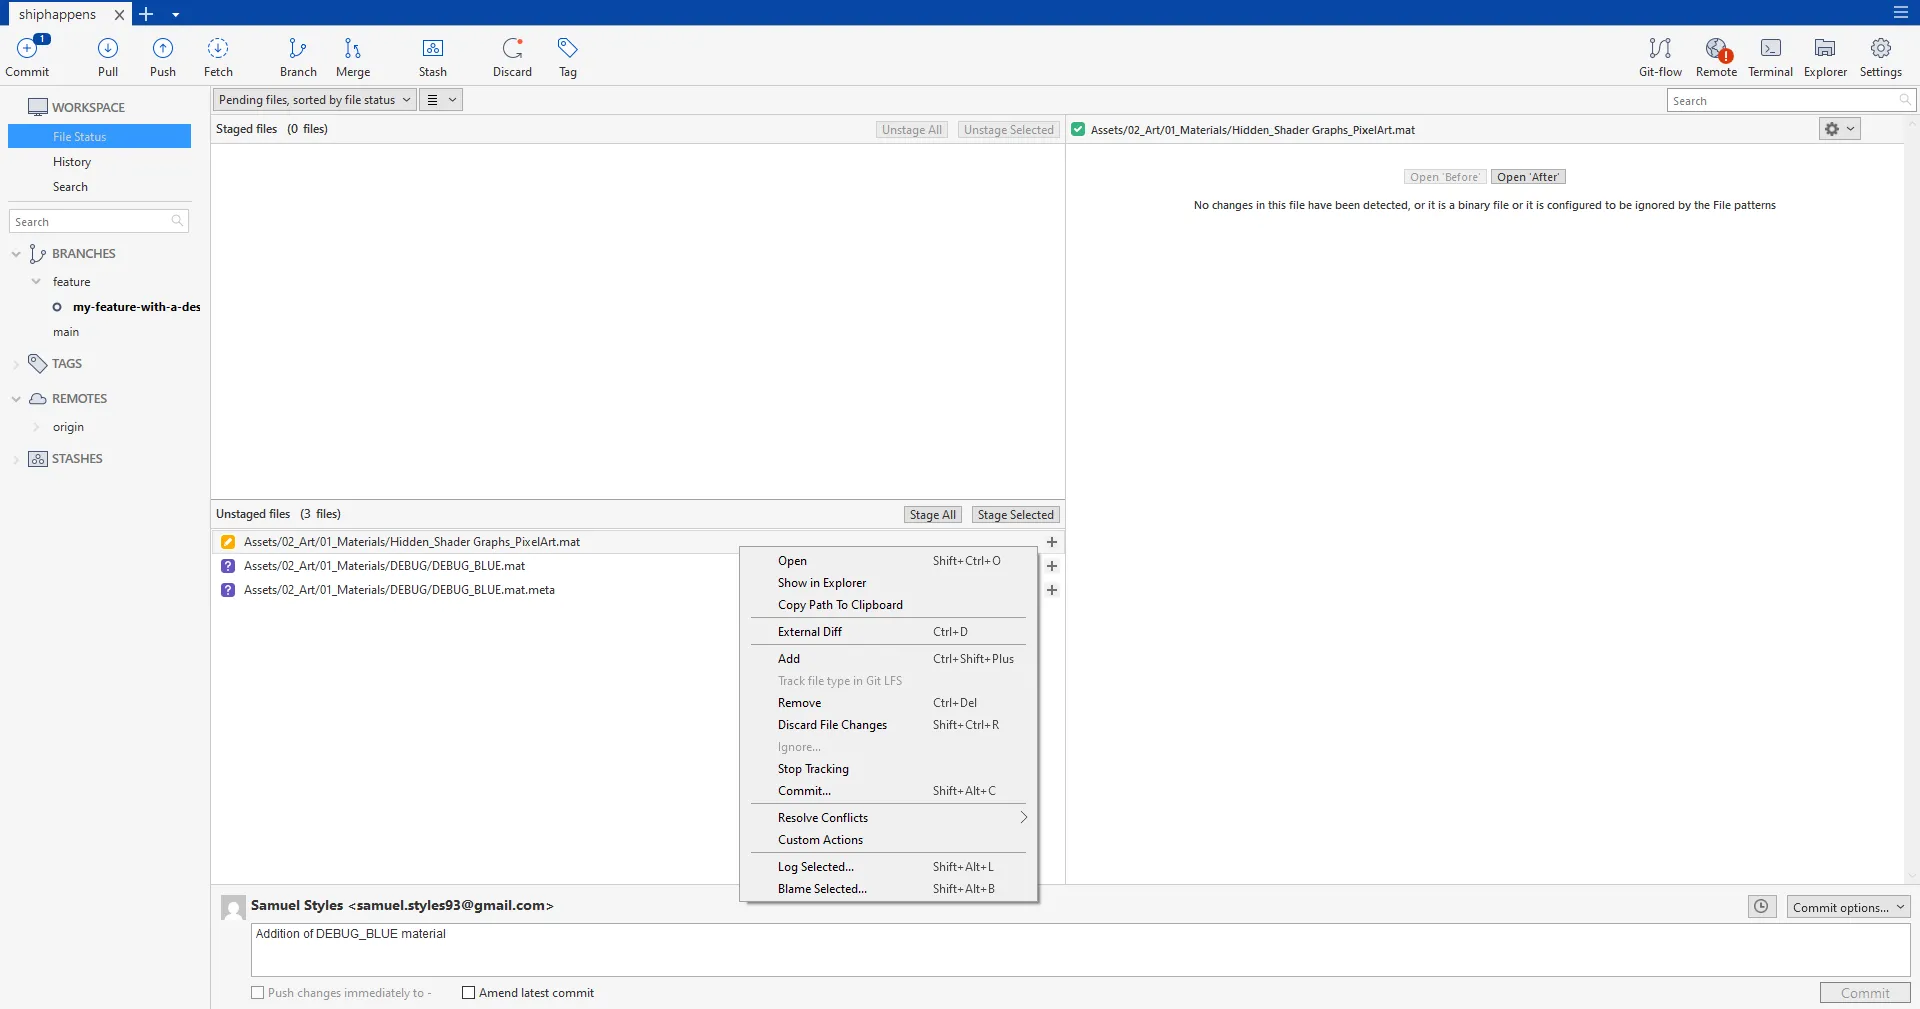
The bottom pane shows all modified files split into two areas:
- Unstaged files — changes not yet included in the next commit
- Staged files — changes that will be saved in the next commit
You can:
- Click Stage All to stage every modified file at once
- Stage individual files by selecting them and clicking Stage Selected or using the little [+] sign
- Discard file changes by right-clicking a file → Discard (this permanently reverts the file to its last committed state — use with care)
- Remove a file from the project entirely by right-clicking → Remove
Enter a commit message and commit
Type your commit message in the text box at the bottom. A good message:
- Uses the present tense: “Add”, “Fix”, “Update”
- Describes what changed and, when relevant, why
- Stays under ~70 characters
Click Commit to save the snapshot locally.
Push to remote
Once you have one or more commits ready, click the Push button in the toolbar. Select the remote branch (it will default to the same name as your local branch) and confirm.
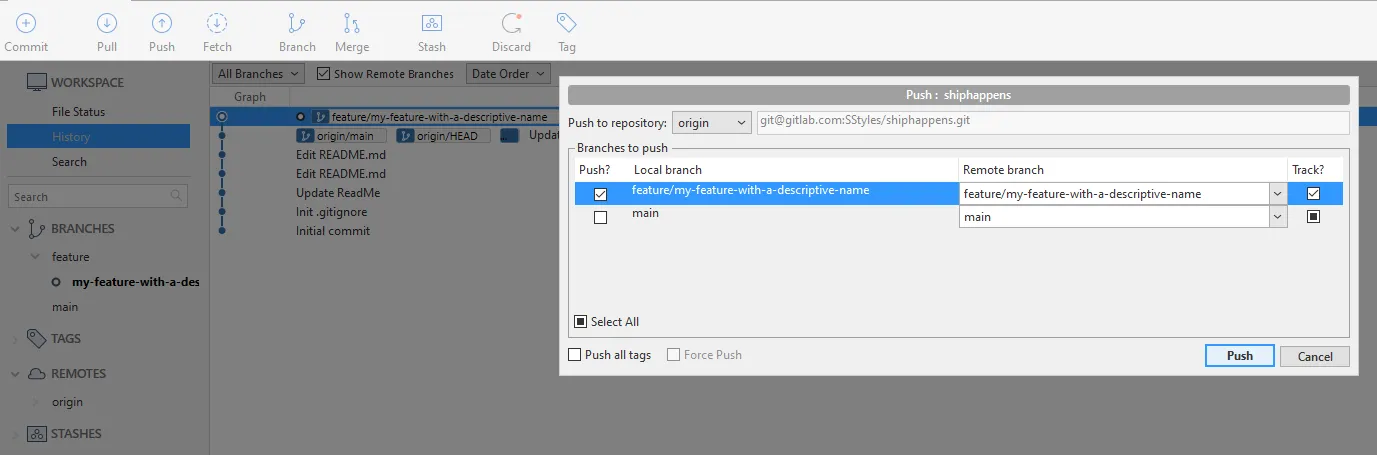
The first push creates the branch on the remote. Subsequent pushes on the same branch require no extra configuration.
3. Create a Merge Request on GitLab
With your branch pushed, open GitLab in your browser and navigate to your project.
Open the Merge Request form
GitLab will usually show a banner at the top: “You pushed…”.
Click [Create Merge Request].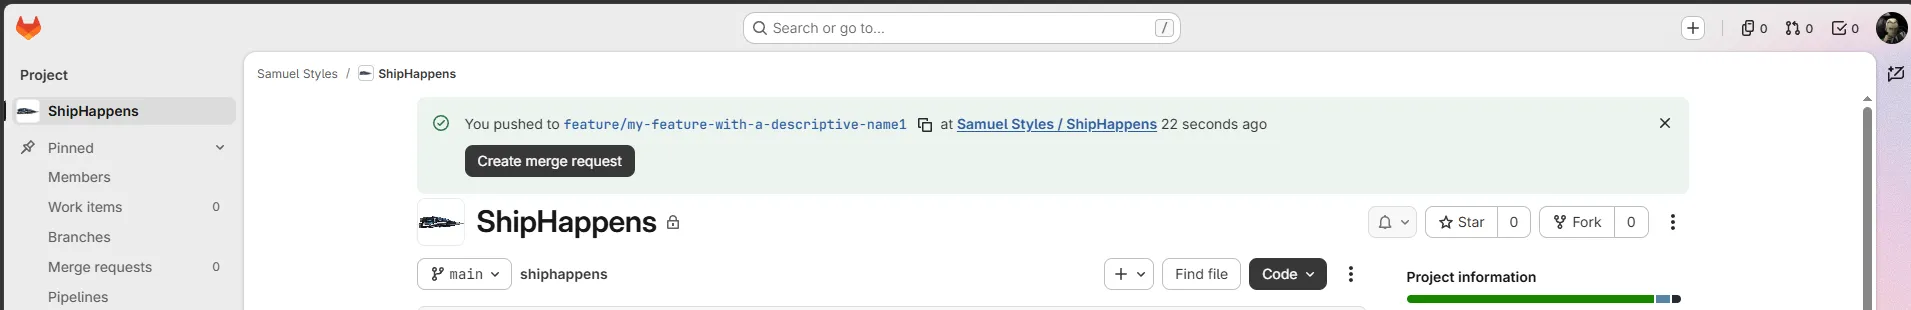
Alternatively go to Merge Requests → New Merge Request, select your source branch and
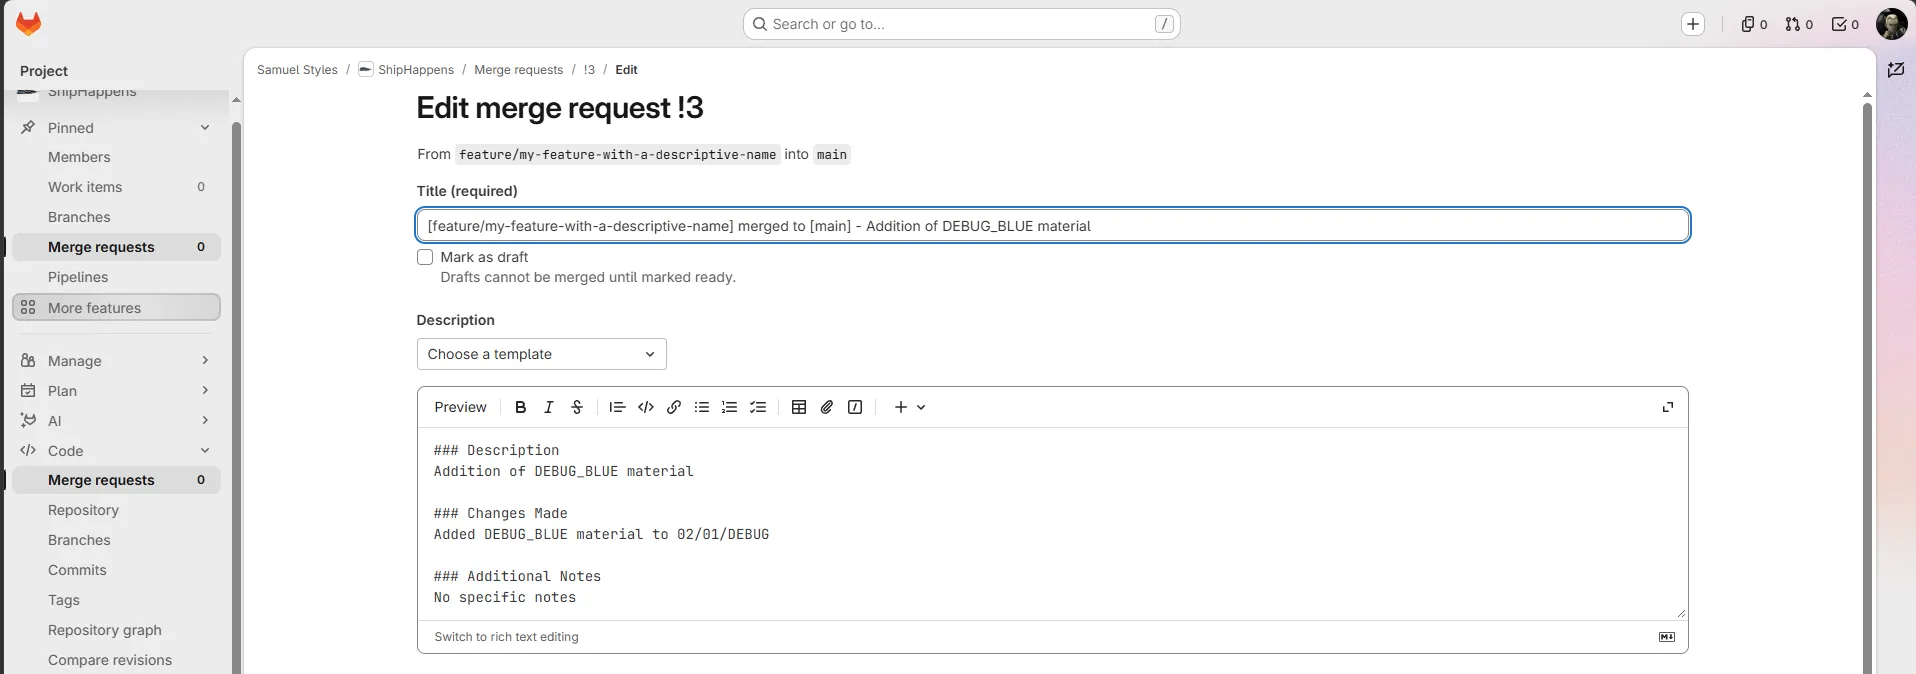
mainas the target.Fill in the description
Give the MR a clear title that mirrors the branch name intent.
For the description, use a template if your project has one configured. It prompts you for the sections reviewers need:
### Description
This merge request addresses, and describe the addition or modification of a feature.
(e.g. Addition of [feature], Update of [feature],...)

### Changes Made
Describe the modification made to the project.
(e.g. Addition of [feature] in folder 00/01/NameOfFolder)

### Additional Notes
Include any extra information or considerations for reviewers.
This can be leaved blank if not specific attention is required.
A well-written description saves reviewers time and avoids back-and-forth.
Set Assignee and Reviewer
- Assignee — the person responsible for the MR
(usually a team lead) - Reviewer — the teammate(s) who will review the code before it merges
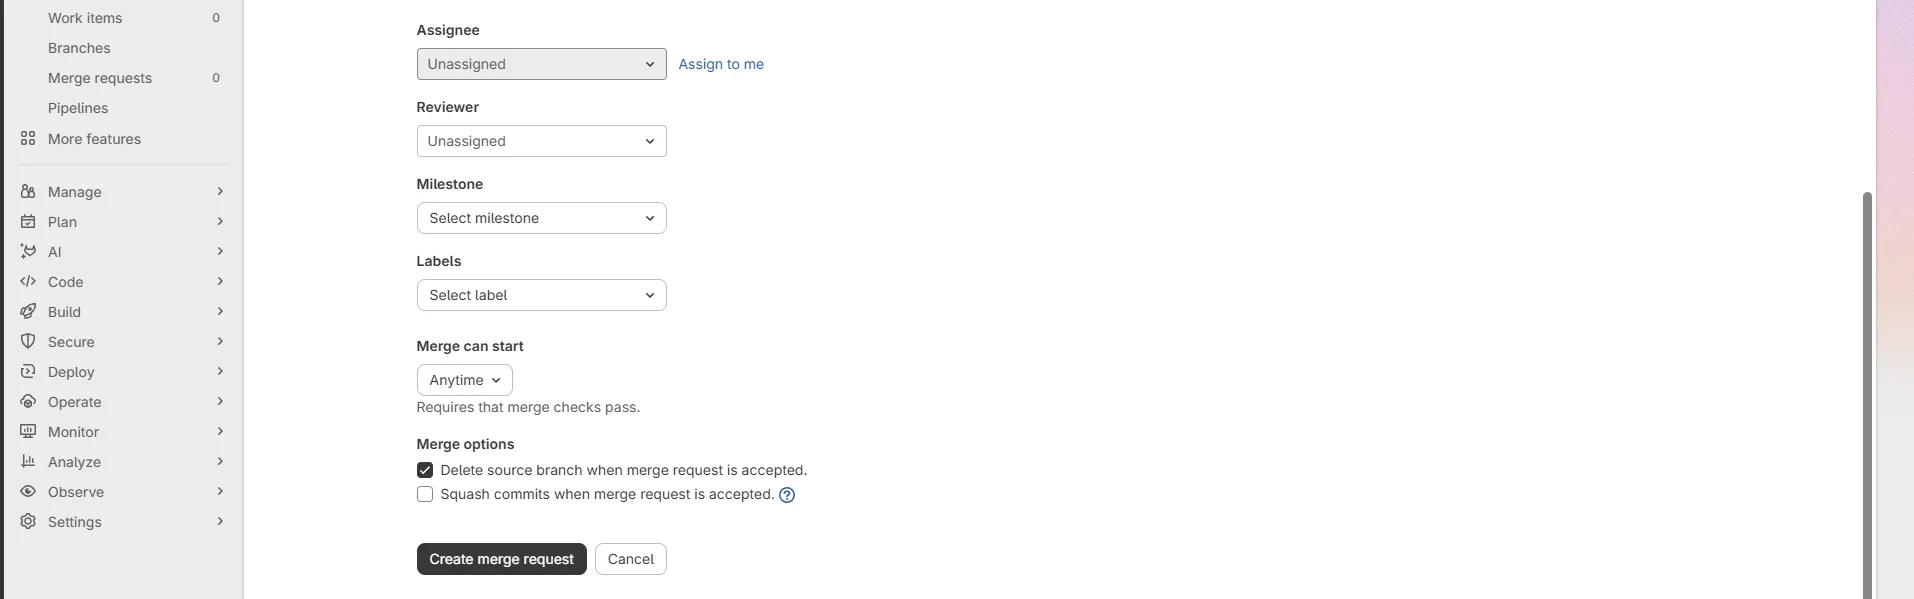
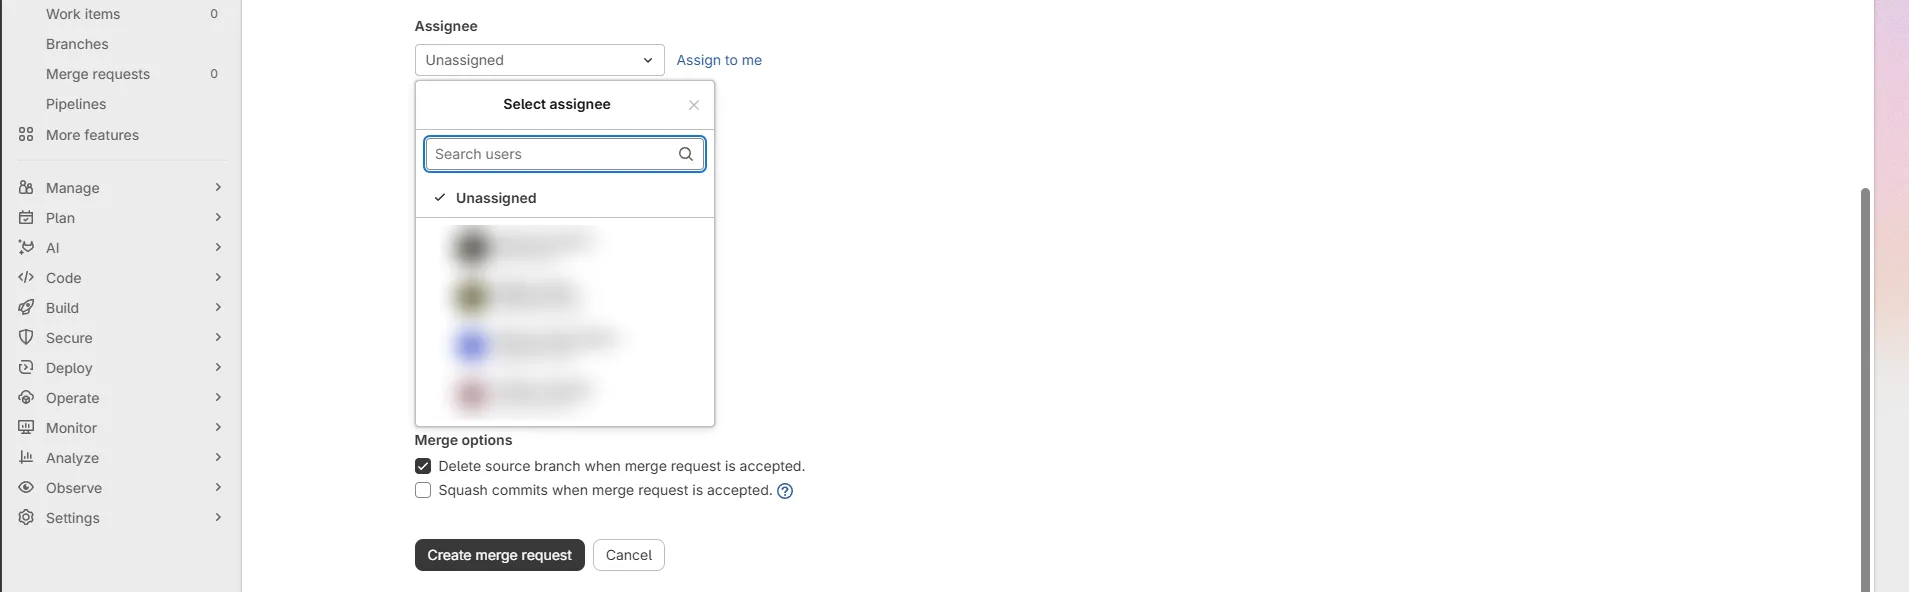
Click Create Merge Request to submit. The assigned reviewers will receive a notification.
4. Reviewer: Approve and Merge
If you are the reviewer, GitLab will notify you by email or in-app notification.
Go to Merge Requests in the GitLab sidebar and click on the MR assigned to you.
Read through the Changes tab — look at the diff, check for correctness, edge cases, and consistency with the project conventions. Leave inline comments if anything needs addressing.
When everything looks good, click Approve to signal your sign-off, then click Merge to merge the branch into
main.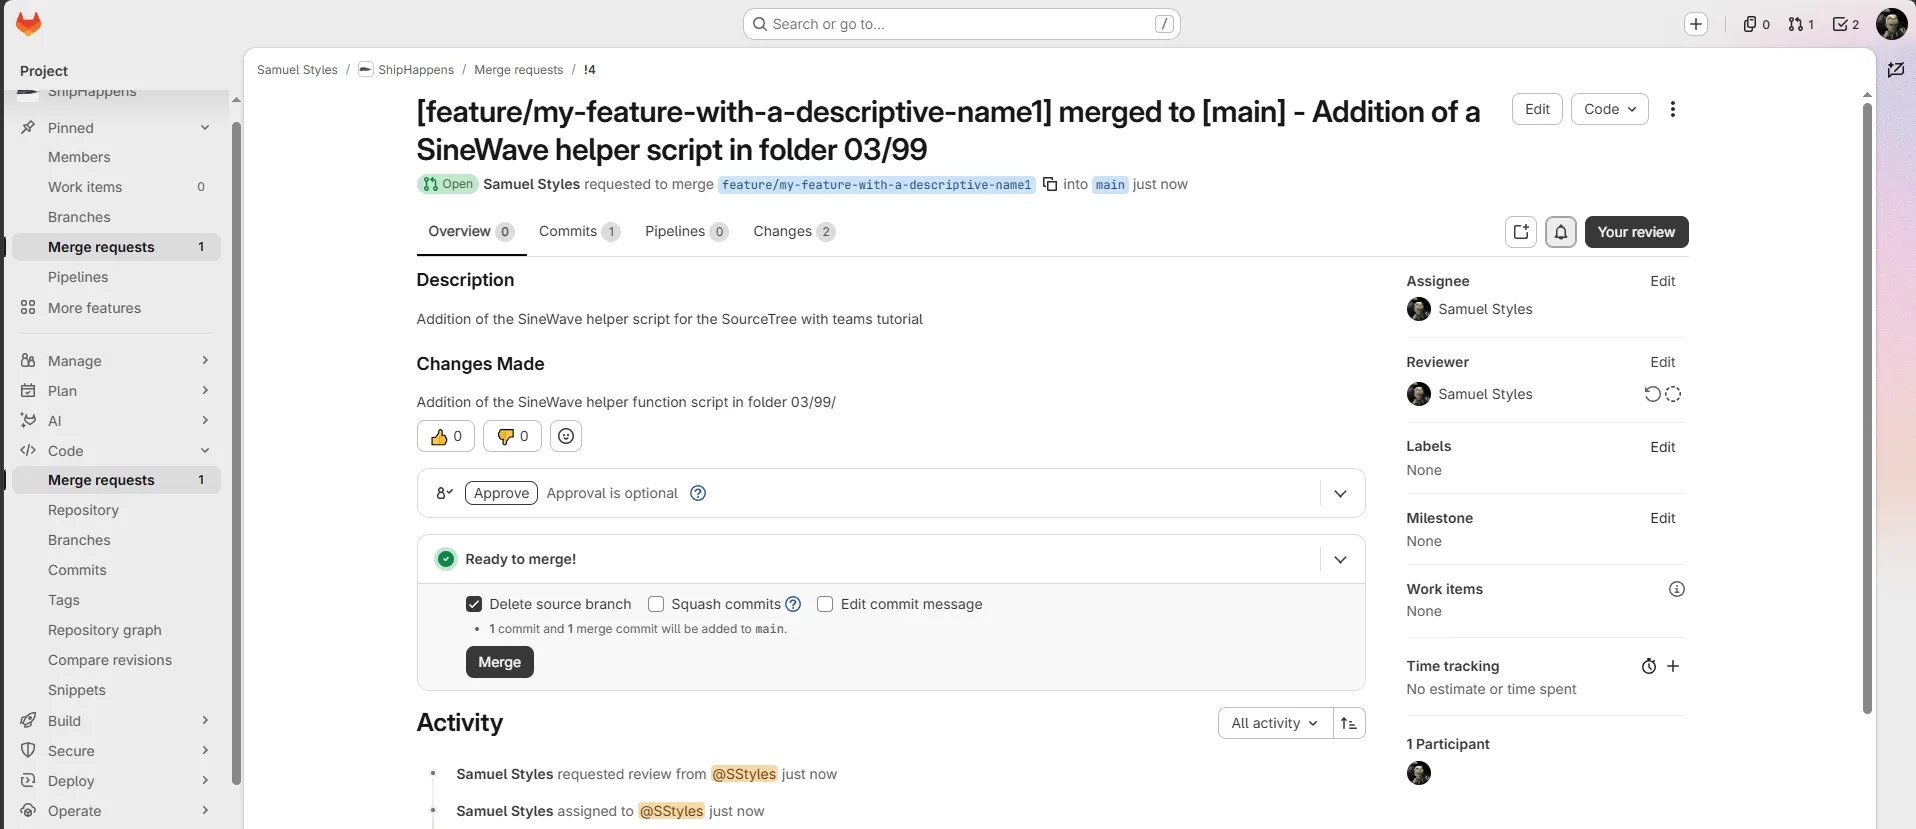
Once merged, the feature branch on the remote is no longer needed. GitLab offers an option to delete the source branch automatically on merge — enable it to keep the remote clean.
5. Clean Up — Delete Branch and Pull main
After the MR is merged, sync your local repository and remove the feature branch.
Pull main
Switch back to main in SourceTree and click Pull to bring in the merge commit.
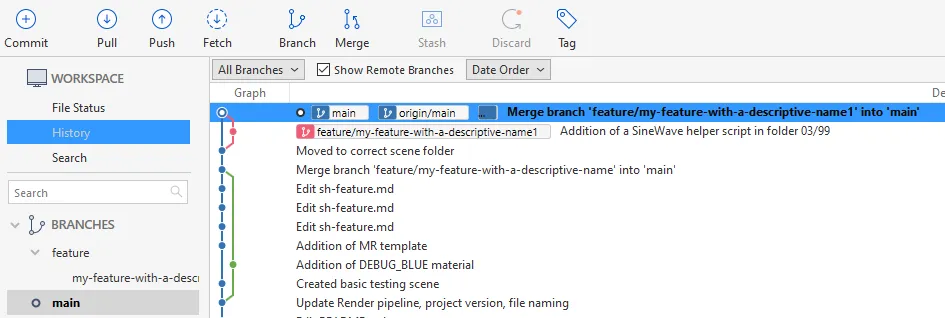
Delete the local branch
In the left sidebar, right-click your feature branch → Delete branch… and confirm.
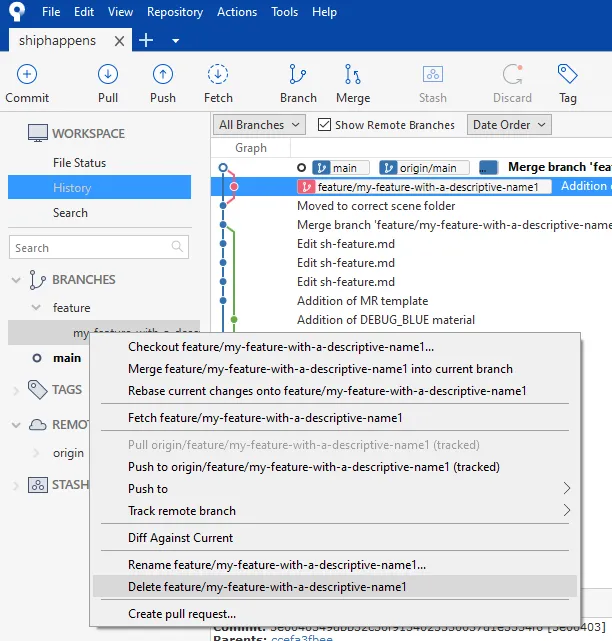
Optional — Prune tracking branches automatically
If your team deletes branches on the remote after merging, SourceTree can clean up the stale tracking references automatically so you never have to delete them manually.
Go to Repository → Repository Settings → Remotes and enable Prune tracking branches on fetch.
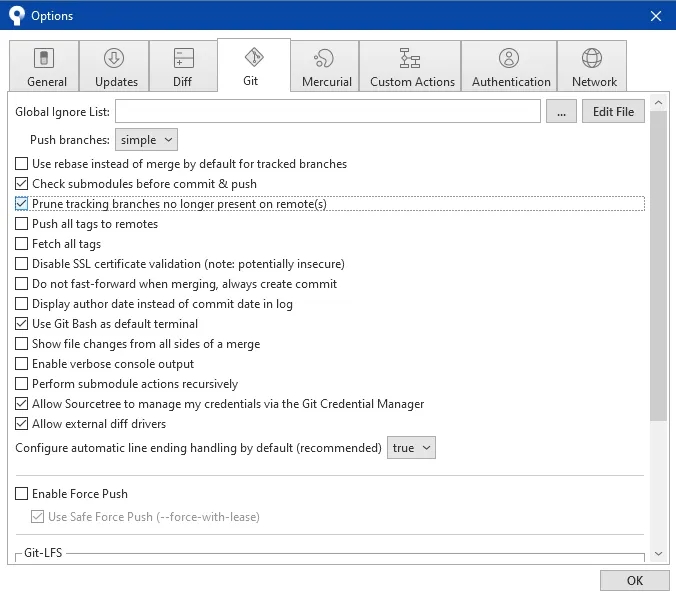
With pruning enabled, every Pull or Fetch removes any local tracking reference for a branch that no longer exists on the remote. You will not have to manually delete
origin/feature/my-feature-with-a-descriptive-nameafter it has been merged and deleted on GitLab.
Summary
Step Action SourceTree / GitLab 1 Pull latest mainSourceTree → Pull 1 Create feature branch SourceTree → Branch 2 Stage, commit, push SourceTree → File Status → Commit → Push 3 Open MR, fill description GitLab → Merge Requests → New 3 Set assignee and reviewer GitLab MR form 4 Review, approve, merge GitLab → Merge Requests → Merge 5 Pull main, delete local branch SourceTree → Pull → Delete branch 5 (Optional) Enable prune SourceTree → Repository Settings Created on September 2026 -
Git — Version Control for Teams
Git is a version control system — a tool that records every change made to your project over time. Think of it like a save history, but smarter: multiple people can work on the same files simultaneously without overwriting each other’s work. Every change is tracked, attributable, and reversible.
Without git, teams share files over email or cloud drives and conflicts are resolved manually. With git, the whole history lives in the project itself.
Installation
Windows
Download Git for Windows from git-scm.com. Accept the defaults during setup. This installs:
gitavailable in PowerShell and Command Prompt- Git Bash — a terminal emulator with Unix-style commands
Open Git Bash and verify the installation:
git --version
macOS
macOS ships with a minimal git. Install the full version via Homebrew:
# Install Homebrew (skip if you already have it)
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"

brew install git
git --version
Linux (Debian / Ubuntu)
sudo apt update && sudo apt install git
git --version
For Fedora / RHEL:
sudo dnf install git
Initial Configuration
Before using git, tell it who you are. This information is attached to every commit you make.
git config --global user.name "Your Name"
git config --global user.email "you@example.com"
These are stored in
~/.gitconfig. To verify:git config --list #or git config -l
SSH Keys
What is an SSH Key?
When you push code to GitHub or GitLab, the platform needs to verify your identity. You could use a username and password every time — but SSH keys are more secure and require no typing.
An SSH key is a pair of files:
File Role Private key Stays on your machine. Never share it. Public key Uploaded to GitHub/GitLab. Acts like a padlock. Authentication works like a padlock: GitHub holds the lock (public key), you hold the key (private key). If they match, you’re in — no password needed.
Generating a Key
Open your terminal (Git Bash on Windows, Terminal on Mac/Linux):
ssh-keygen -t ed25519 -C "you@example.com"Flag Meaning -t ed25519ed25519 encryption algorithm — modern and recommended -C "..."A label to identify the key (use your email) Press Enter to accept the default file location. You can optionally set a passphrase for an extra layer of security.
Where the Key is Stored
File Path Description id_ed25519~/.ssh/id_ed25519Your private key — never share this id_ed25519.pub~/.ssh/id_ed25519.pubYour public key — this goes to GitHub/GitLab On Windows,
~isC:\Users\YourName. On Mac/Linux, it’s/home/yourname.Display your public key to copy it:
cat ~/.ssh/id_ed25519.pubThe output starts with
ssh-ed25519 AAAA...— copy the entire line.
Adding the Key to GitHub
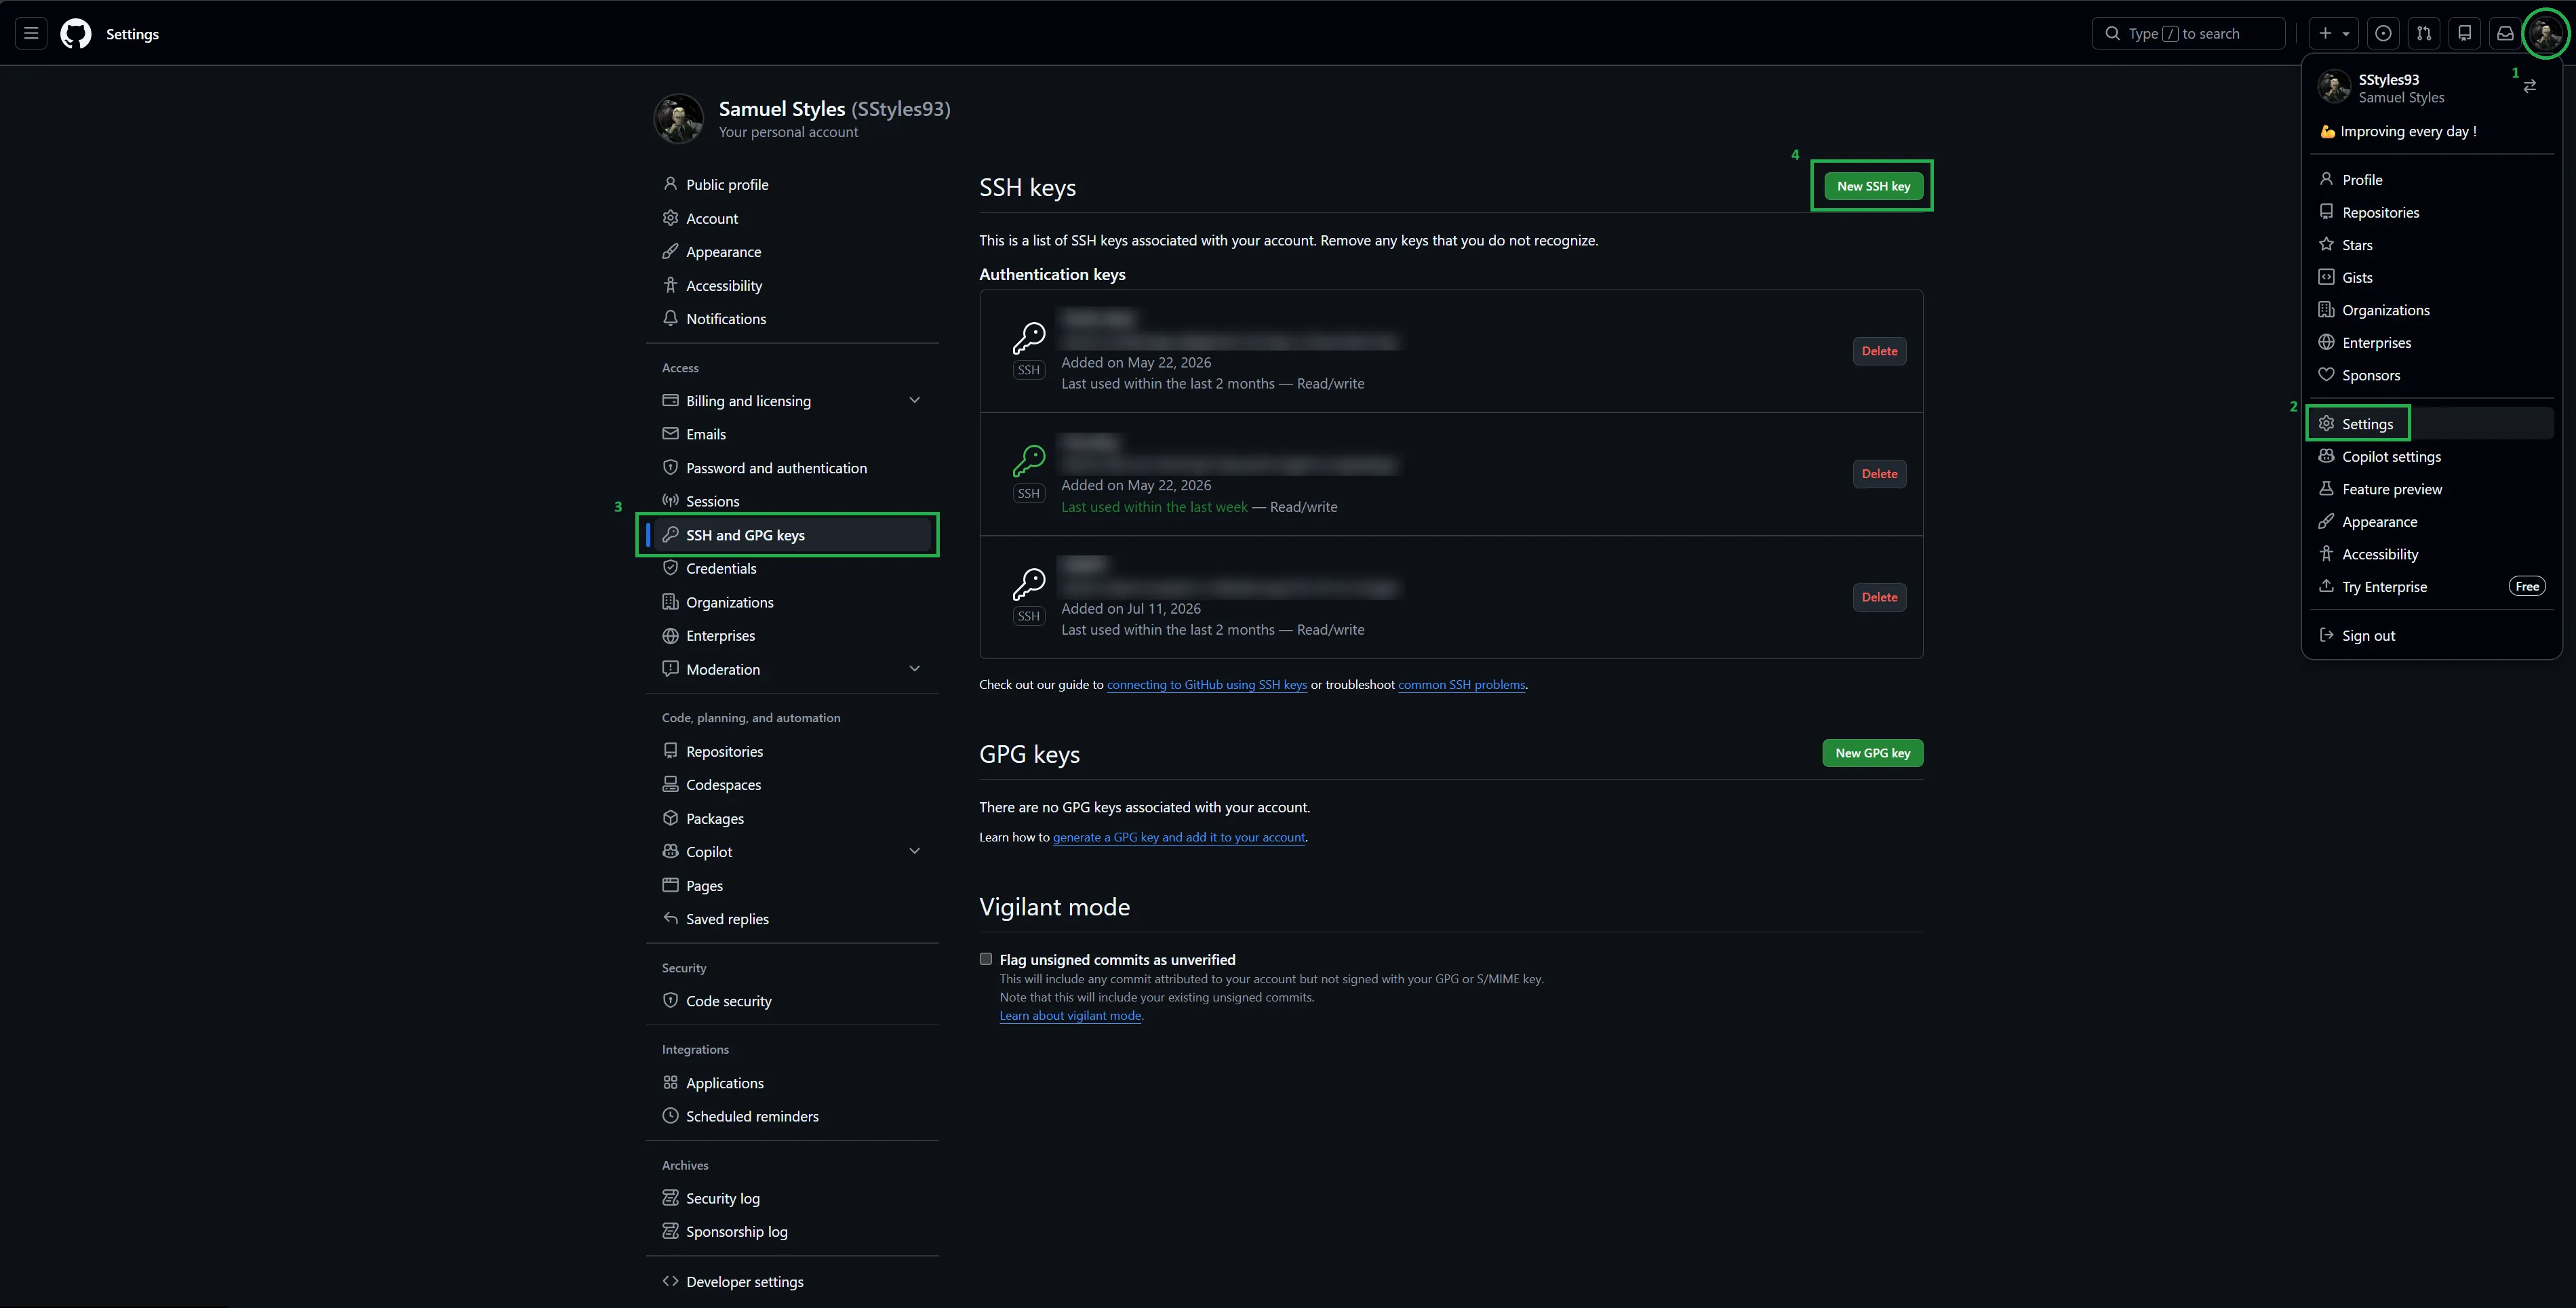
- Go to GitHub → Settings → SSH and GPG keys
- Click New SSH key
- Give it a title (e.g. “My Laptop”)
- Paste your public key in the Key field
- Click Add SSH key
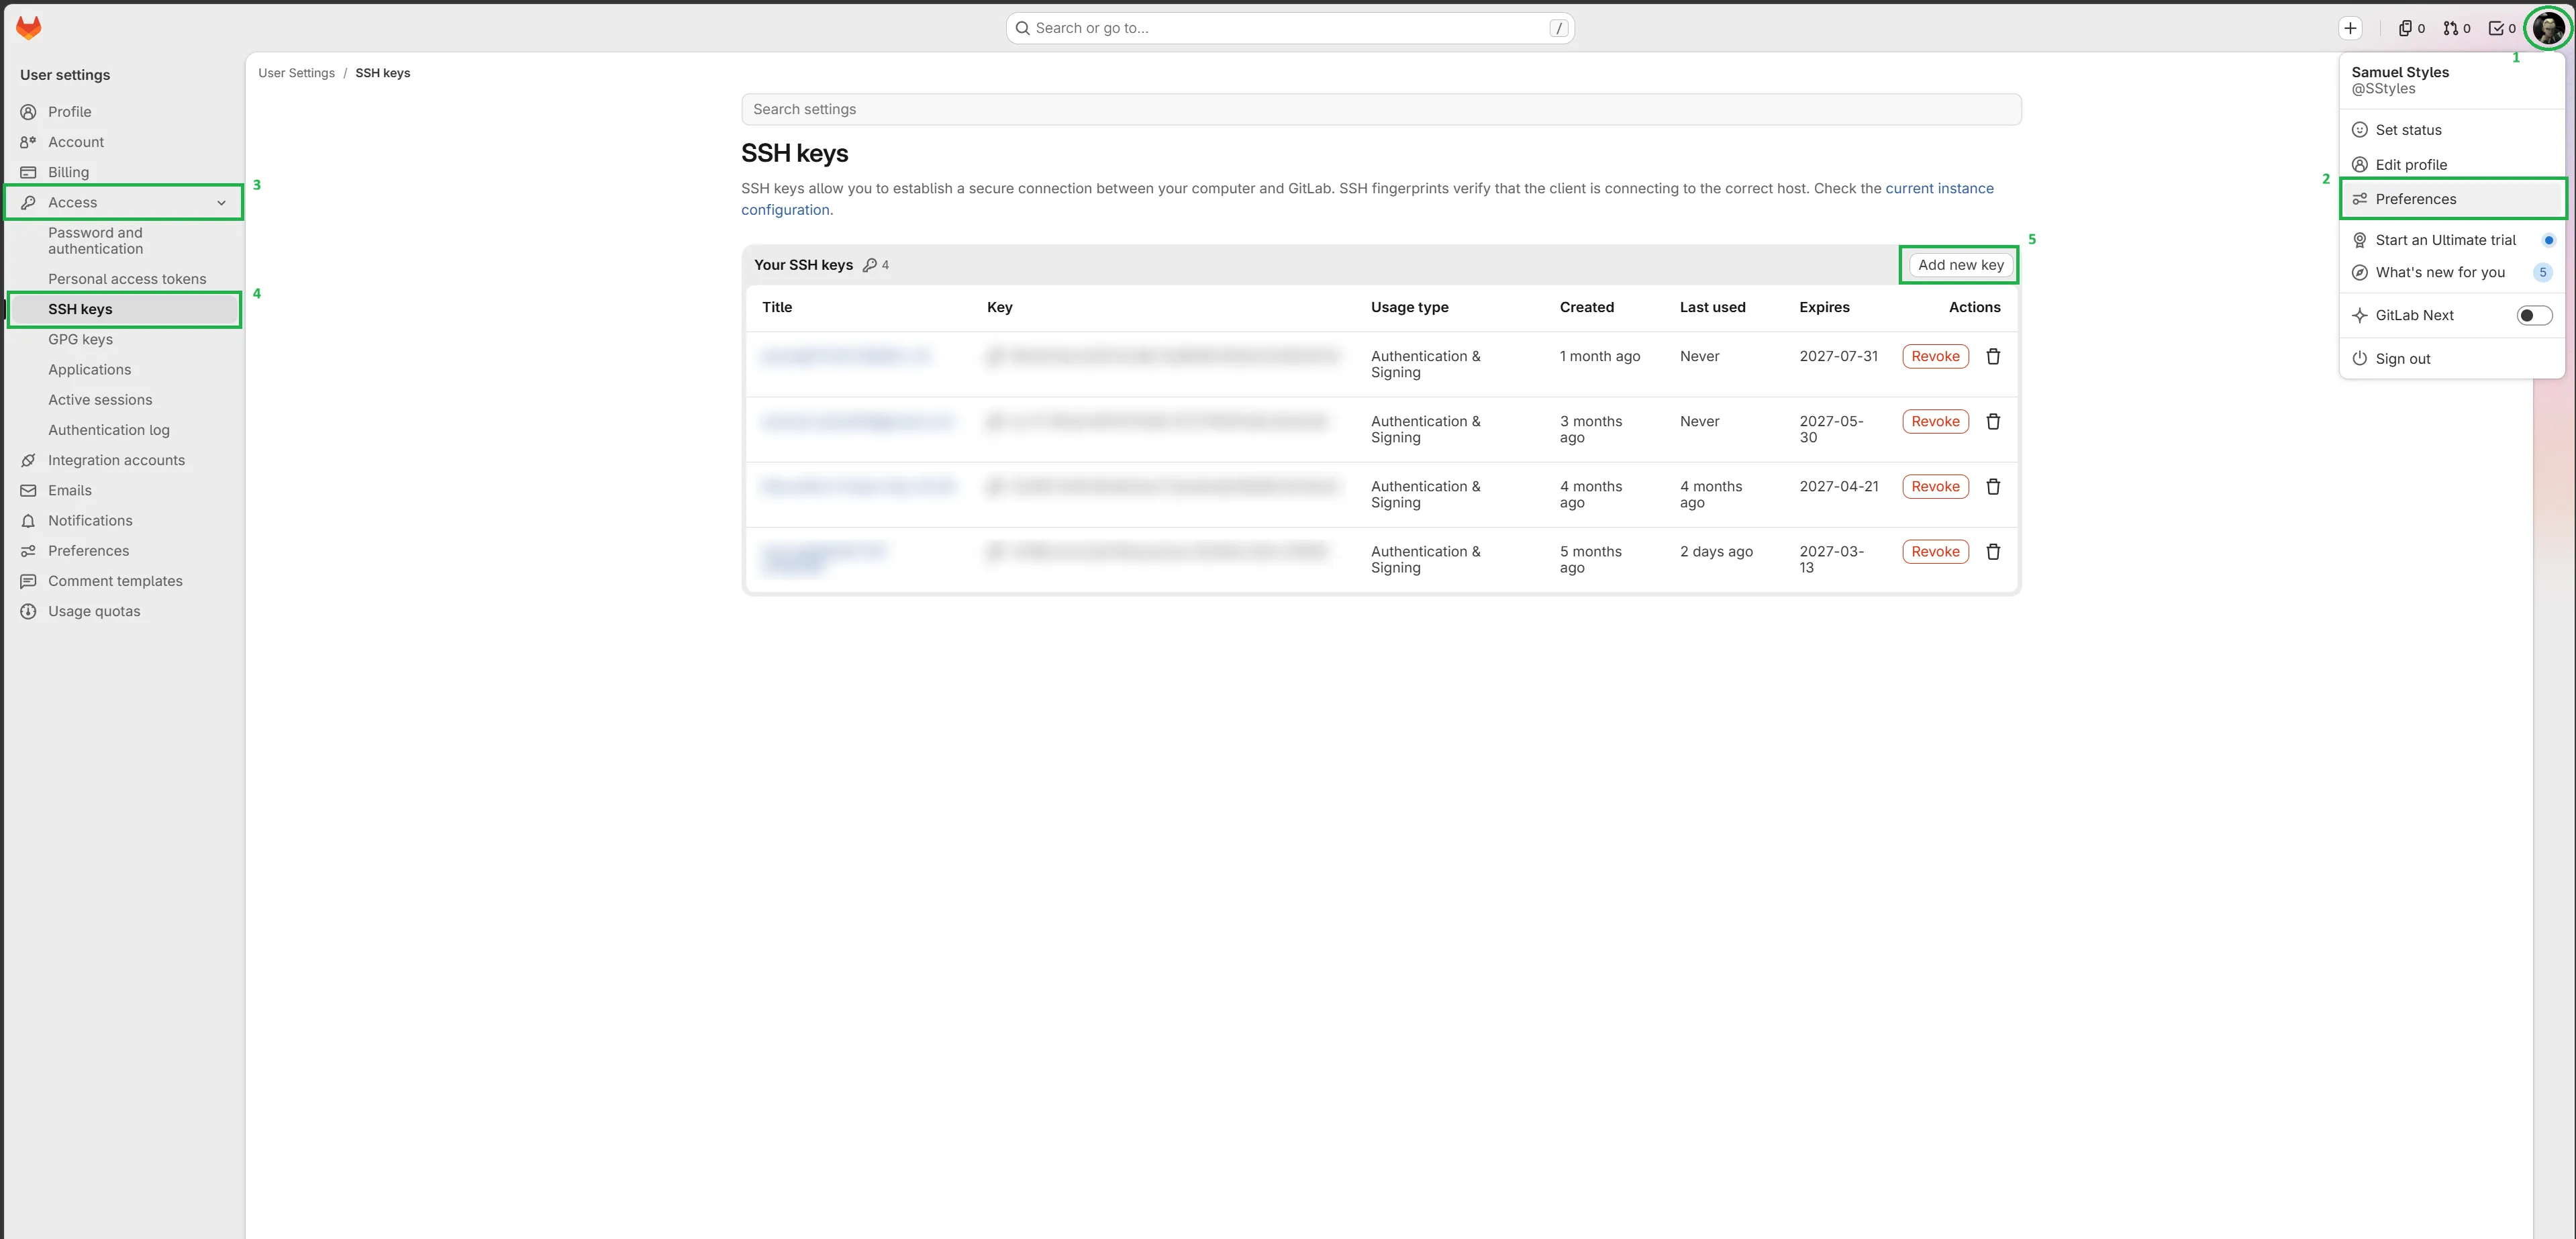
Adding the Key to GitLab
- Go to GitLab → Preferences → SSH Keys
- Paste your public key in the Key field
- Give it a title and optionally an expiry date
- Click Add key
Testing the Connection
ssh -T git@github.com   # GitHub
ssh -T git@gitlab.com   # GitLab
A successful response looks like:
Hi "username"! You've successfully authenticated, but GitHub does not provide shell access.In case of error “-v” can be added to the command for verbose output (more detailed)
Basic Commands
Initializing or Cloning a Repository
Start git tracking in an existing folder:
git initOr download an existing repository from GitHub/GitLab:
git clone git@github.com:username/repo-name.gitThe SSH URL (starting with
git@) uses your SSH key. HTTPS URLs also work but will prompt for credentials every time.git status
The most important command. Shows the current state of your working directory:
git statusCategory shown Meaning Untracked files New files git doesn’t know about yet Changes not staged Modified files, not yet added Changes to be committed Staged and ready to commit Run
git statusconstantly — it always tells you what to do next.git add
Stage files to include in the next commit:
git add file.txt          # stage one file
git add src/              # stage an entire folder
git add .                 # stage everything in the current directory
Staging is a deliberate step — it lets you choose exactly what goes into each commit.
git commit
Save a snapshot of your staged changes:
git commit -m "Add login form validation"A good commit message:
- Written in the present tense: “Add”, “Fix”, “Update”
- Describes what changed and ideally why
- Stays under ~70 characters
# Too vague
git commit -m "fix"

# Clear and useful
git commit -m "Fix crash when user has no profile picture"
git push
Upload your local commits to the remote repository:
git push                           # push current branch to its remote
git push -u origin feature/login   # link the branch to remote and push (first time)
The
-uflag sets the upstream so futuregit pushcalls work without specifying the branch name.git pull
Download and apply the latest changes from the remote:
git pullThis is
git fetch(download) +git merge(apply) in one command. Run it at the start of each session to stay in sync with your teammates.git branch
Branches let you work on a feature in isolation without touching the main codebase.
git branch                         # list all local branches
git branch feature/login           # create a new branch
git checkout feature/login         # switch to a branch
git checkout -b feature/login      # create and switch in one step
git branch -d feature/login        # delete a branch (after merging)
Since git 2.23,
git switchis the modern, dedicated command for switching branches. It does exactly whatgit checkoutdoes for branches — nothing else — making it clearer to read:git switch feature/login # switch to a branch git switch -c feature/login # create and switch in one step (-c = create)Both
checkoutandswitchwork.switchis preferred in new workflows.git reset
Remove files from staging or roll back to a previous state.
git reset file.txt # unstage a file, keep the changes in your working directory git reset # unstage everything, keep all changes git reset --hard <commit> # move HEAD to <commit> and discard all changes<commit>can be a commit hash, branch name, or tag:git reset --hard abc1234 # reset to a specific commit git reset --hard main # reset to the tip of the main branch git reset --hard v1.2.0 # reset to a tagged releaseWarning:
--hardpermanently discards all uncommitted changes. Any work not yet committed will be lost.git revert
Create a new commit that undoes the changes introduced by a previous commit:
git revert abc1234 # undo a specific commit by creating a new oneUnlike
git reset,git revertdoes not rewrite history — the original commit stays. This makes it safe to use on shared branches (likemain) where teammates have already pulled the commit.Command Rewrites history? Safe on shared branches? git reset --hardYes No git revertNo Yes
Simple Workflow
The simplest team workflow if the “Feature Branch”. Good for small teams and projects without fixed release cycles.
Why Branches Matter
Without branches, everyone pushes directly to
main. This leads to conflicts, broken builds, and code that ships without review. Branches give each feature its own safe workspace.
How it works
mainis always stable and deployable- Every feature or fix lives on its own branch
- Branches are merged back into
mainvia a Pull Request or Merge Request
main       ──────────────────────────────────────────●──────
            ↓ (pull)                                 ↑ (push)
feature    ────────●──────●──────●──────●────────────●
                (commits)               (ready to merge)
For Pull Resquests or Merge Requests see Professional Workflow — Pull Requests and Merge Requests
Branch naming convention
feature/user-login
bugfix/null-pointer-crash
hotfix/payment-gateway-timeout
Step-by-step workflow
# 1. Make sure main is up to date
git switch main
git pull

# 2. Create your feature branch
git switch -c feature/user-login

# 3. Work and commit regularly
git add .
git commit -m "Add login form"

# 4. Push to remote when ready
git push -u origin feature/user-login

# 5. Open a Pull Request (GitHub) or Merge Request (GitLab) on the platform
# 6. Once approved and merged on the platform, clean up locally
git switch main
git pull
git branch -d feature/user-login
Advanced Workflows
Structured Workflow — Gitflow
For larger teams with scheduled release cycles, Gitflow adds more structure between your work and production.
Branch Branched from Purpose main— Production-ready code only. Always stable. developmainIntegration point for completed features. feature/*developIndividual feature work. release/*developStabilization and testing before a release. hotfix/*mainEmergency production fixes. main ──────●───────────────────────────────────────────●─── ↓ (pull) ↑ (push) develop ──────────●─────────────────────────────────●───────── ↓ (pull) ↑ (push) feature/X ──────●──────●──────●────────────●Step-by-step workflow:
# 1. Start from develop — never from main
git switch develop
git pull

# 2. Create a feature branch off develop
git switch -c feature/payment-gateway

# 3. Work and commit
git add .
git commit -m "Add Stripe integration"

# 4. Push and open a MR/PR targeting develop (not main)
git push -u origin feature/payment-gateway

# 5. Once merged into develop, prepare a release branch
git switch develop
git pull
git switch -c release/1.2.0

# 6. Fix last-minute issues on the release branch
git commit -m "Fix edge case in payment form"

# 7. Merge into main AND back into develop
git switch main
git merge release/1.2.0
git switch develop
git merge release/1.2.0
git branch -d release/1.2.0

# 8. Tag the release on main
git switch main
git tag -a v1.2.0 -m "Release 1.2.0"
git push origin v1.2.0
Emergency hotfix directly on production:
git switch main
git switch -c hotfix/crash-on-login
# ... fix the bug ...
git commit -m "Fix crash on login for users with no avatar"
git switch main
git merge hotfix/crash-on-login
git switch develop
git merge hotfix/crash-on-login      # keep develop in sync
git branch -d hotfix/crash-on-login
When to use which:
Situation Recommendation Small team, continuous deployment Simple feature branch Larger team, versioned releases Gitflow Open-source with many contributors Gitflow or fork-based model
Professional Workflow — Pull Requests and Merge Requests
A Pull Request (GitHub) and Merge Request (GitLab) are the same concept — a formal request to merge a branch. The name differs by platform, the workflow is identical.
Their purpose goes beyond just merging code:
- Review changes before they reach production
- Discuss the approach with teammates
- Catch bugs early through peer review
- Trigger automated checks (tests, linting, CI/CD)
Step-by-step workflow:
# 1. Push your branch and open the PR/MR on GitHub or GitLab
git push -u origin feature/player-dash

# 2. Fill in the description (see template below), assign reviewers

# 3. Address review comments — push new commits to the same branch
git add .
git commit -m "Address review: clamp dash speed to prevent wall clipping"
git push

# 4. Once approved, merge on the platform (not locally)

# 5. Clean up locally
git switch main
git pull
git branch -d feature/player-dash
Writing a useful PR/MR description:
A good description saves your reviewers time — they shouldn’t need to read every line to understand the context:
## What this does
Adds a dash mechanic to the player — triggered by Shift, with a 0.8s cooldown and a short invincibility window.

## Why
Movement felt sluggish in playtests. Players needed a way to dodge attacks and close distance quickly.

## How to test
1. Enter Play mode
2. Hold Shift while moving in any direction
3. Verify the player dashes and the cooldown prevents spam
4. Walk into an enemy during the dash — verify no damage is taken
Rules that matter:
Protect
main. Never push directly tomain. On GitHub: Settings → Branches → Branch protection rules. Require at least one reviewer approval before any merge.One PR = one concern. A PR that adds a feature, refactors three unrelated files, and fixes a separate bug is hard to review. Keep PRs focused on a single change.
Review seriously. Code review is not a rubber stamp. Read the code, think about edge cases, ask questions. It’s how bugs get caught and how the whole team learns.
Commit often. Small, frequent commits are easier to review and easier to revert if something goes wrong.
Keep your branch up to date. If
mainmoves forward while you’re on a feature branch, bring those changes in:git switch feature/player-dash git merge main # merge main into your branchOr with rebase (cleaner history):
git rebase main
Quick Reference
Command What it does git initInitialize a new repository git clone <url>Download an existing repository git statusShow what’s changed git add <file>Stage a file for the next commit git add .Stage all changes git commit -m "..."Save a snapshot with a message git pushUpload commits to the remote git push -u origin <branch>Link and push a branch for the first time git pullDownload and apply remote changes git branch <name>Create a new branch git checkout <branch>Switch to a branch (classic) git checkout -b <name>Create and switch (classic) git switch <branch>Switch to a branch (modern) git switch -c <name>Create and switch (modern) git merge <branch>Merge a branch into the current one git rebase <branch>Reapply commits on top of another branch git resetUnstage files, keep changes git reset --hard <commit>Move HEAD to a commit and discard all changes git revert <commit>Undo a commit by creating a new one (safe for shared branches) ssh-keygen -t ed25519 -C "..."Generate an SSH key pair Created on September 2026 -
C — Debugging with Valgrind
Valgrind is a dynamic analysis tool that runs your program in a controlled environment and reports every memory error — leaks, invalid accesses, and use of uninitialised values — with the exact line where they happened.
Step 1 — Compile with Debug Symbols
Like GDB, Valgrind needs the
-gflag to show source lines instead of raw addresses:gcc -Wall -Wextra -Werror -g main.c -o my_programStep 2 — Run Under Valgrind
valgrind ./my_programThis runs Memcheck (Valgrind’s default tool) and prints a summary at the end. For thorough leak detection use the full set of flags:
valgrind --leak-check=full --show-leak-kinds=all --track-origins=yes -s ./my_programFlag Effect --leak-check=fullreport every individual leaked block, not just totals --show-leak-kinds=allinclude definitely, indirectly, possibly lost, and still reachable --track-origins=yesshow where an uninitialised value was created -sprint a short error summary at the end Reading the Output
A clean run ends with:
LEAK SUMMARY:
   definitely lost: 0 bytes in 0 blocks
   indirectly lost: 0 bytes in 0 blocks
     possibly lost: 0 bytes in 0 blocks
   still reachable: 0 bytes in 0 blocks
        suppressed: 0 bytes in 0 blocks

ERROR SUMMARY: 0 errors from 0 contexts
Any non-zero number is a problem to fix.
Types of Errors
Memory Leak —
definitely lostMemory was allocated but never freed, and no pointer to it remains:
int *arr = malloc(10 * sizeof(int));
// forgot to free(arr)
LEAK SUMMARY: definitely lost: 40 bytes in 1 blocksFix: add
free(arr)before the program exits.Invalid Read / Write
Accessing memory outside an allocated block — classic buffer overflow or off-by-one:
int *arr = malloc(3 * sizeof(int));
arr[3] = 99;   // index 3 is out of bounds (valid: 0, 1, 2)
Invalid write of size 4 at 0x... main (main.c:6) Address 0x... is 0 bytes after a block of size 12 alloc'dFix: check array sizes and loop bounds.
Use of Uninitialised Value
Reading a variable that was declared but never assigned:
int x;
if (x > 0)   // x has no defined value
    printf("positive\n");
Conditional jump or move depends on uninitialised value(s) at 0x... main (main.c:5)With
--track-origins=yesValgrind also reports wherexwas allocated, making it much easier to trace the root cause.Invalid Free
Freeing a pointer that was already freed, or one that was never malloc’d:
free(ptr);
free(ptr);   // double free
Invalid free() / delete / delete[] / realloc() at 0x... free (in valgrind) by 0x... main (main.c:8) Address 0x... is 0 bytes inside a block of size 4 free'dFix: set
ptr = NULLimmediately afterfree(ptr).Still Reachable
Memory that was never freed but a valid pointer to it still exists at exit. Technically not a leak (the pointer is accessible), but still sloppy:
char *buf = malloc(64);
// buf is never freed, but main() returns with buf still in scope
These show up under
still reachablein the summary. Free everything before returning frommain.
A Typical Workflow
# Compile
gcc -Wall -Wextra -Werror -g main.c utils.c -o my_program

# Run with full checks
valgrind --leak-check=full --show-leak-kinds=all --track-origins=yes -s ./my_program

# If your program takes arguments
valgrind --leak-check=full --show-leak-kinds=all --track-origins=yes -s ./my_program arg1 arg2
Read the output top to bottom:
- Each error block shows the type, the line, and the call stack
- The LEAK SUMMARY groups leaks by category
- The ERROR SUMMARY gives the total count
Fix errors from the innermost call stack frame up — that is usually the root cause.
Quick Reference
Command / Flag Effect valgrind ./progrun with default Memcheck settings --leak-check=fullreport each leaked block individually --show-leak-kinds=allinclude all leak categories --track-origins=yesshow where uninitialised values come from -sprint error summary at the end definitely lostmalloc’d memory with no surviving pointer — must fix still reachablepointer exists but memory never freed — fix before exit Invalid read/writeout-of-bounds access Uninitialised valuevariable used before being assigned Invalid freedouble free or freeing a non-heap pointer Created on July 2026 -
C — Debugging with GDB
GDB (GNU Debugger) lets you run a C program step by step, inspect memory and variables at any point, and find exactly where and why something goes wrong.
Step 1 — Compile with Debug Symbols
By default GCC strips debug information from the binary. The
-gflag includes it:gcc -Wall -Wextra -Werror -g main.c -o my_programWithout
-g, GDB can still run the program but cannot show source lines, variable names, or meaningful stack frames — just raw addresses.Step 2 — Launch GDB
gdb ./my_programThis opens the GDB prompt
(gdb). The program is loaded but not yet running.If your program takes command-line arguments, use
--argsso GDB does not consume them:gdb --args ./my_program arg1 arg2Everything after the binary name is forwarded to your program when you run
r. Without--args, passing arguments directly togdbwould be interpreted as GDB options.Step 3 — Use GDB TUI for a Visual Layout
gdbtuilaunches GDB with a split-screen terminal UI — source code on top, command prompt below. It is far easier to follow than the plain prompt:gdbtui ./my_program gdbtui --args ./my_program arg1 arg2 # with argumentsThe top pane shows the source file with an arrow pointing at the current line. The bottom pane is the normal GDB command prompt.
Core Commands
r— RunStarts (or restarts) the program. Pass arguments after
rif your program expects them:(gdb) r (gdb) r arg1 arg2The program runs until it hits a breakpoint, crashes, or finishes.
b— BreakpointPauses execution before a specific line or function:
(gdb) b 42          # break at line 42 of the current file
(gdb) b main.c:15   # break at line 15 of main.c
(gdb) b my_function # break at the entry of my_function
List all breakpoints:
(gdb) info bDelete a breakpoint by its number:
(gdb) delete 1n— Next (step over)Executes the current line and moves to the next one. If the current line is a function call, the entire function runs without stepping into it:
(gdb) ns— Step (step into)Like
n, but if the current line calls a function, GDB steps inside that function:(gdb) sUse
swhen you want to follow execution into a function you wrote. Usenwhen you want to skip over library calls or functions you trust.c— ContinueResumes execution at full speed until the next breakpoint (or the end of the program):
(gdb) cprint— Inspect a ValueEvaluates and prints any expression — variable, pointer, arithmetic:
(gdb) print x
(gdb) print *ptr
(gdb) print arr[2]
(gdb) print a + b
You can also modify a variable on the fly:
(gdb) print x = 10disp— Display (auto-print on every step)displayworks likeprintbut re-evaluates and shows the value automatically after everyn,s, orcthat pauses execution:(gdb) disp x (gdb) disp *ptr (gdb) disp arr[i]List active displays:
(gdb) info displayRemove a display by its number:
(gdb) undisplay 1
Useful Extra Commands
bt— BacktraceShows the full call stack at the current point — essential when diagnosing a crash:
(gdb) bt#0 ft_strlen (s=0x0) at ft_strlen.c:6 #1 ft_putstr (str=0x0) at ft_putstr.c:12 #2 main () at main.c:20Read from bottom to top:
maincalledft_putstrwhich calledft_strlenwhere the crash occurred.p/x— Print in HexadecimalUseful for inspecting raw memory values, addresses, and bitfields:
(gdb) p/x flags (gdb) p/x *ptrwatch— WatchpointPauses execution whenever a variable’s value changes — useful for tracking down unexpected mutations:
(gdb) watch xrefresh— Redraw the TUIThe TUI pane can glitch after terminal output or resizing.
refresh(or its shorthandref) redraws it cleanly:(gdb) refresh (gdb) refRun it any time the source window looks garbled.
q— Quit(gdb) q
A Typical Session
# Compile with debug symbols
gcc -Wall -Wextra -Werror -g main.c utils.c -o my_program

# Launch with TUI (with optional arguments)
gdbtui --args ./my_program arg1 arg2
(gdb) b main # break at entry (gdb) r # run until breakpoint (gdb) disp i # watch variable i on every step (gdb) disp *ptr # watch what ptr points to (gdb) n # step over next line (gdb) s # step into the function call (gdb) print result # inspect a value (gdb) c # continue to next breakpoint (gdb) bt # check the call stack after a crash (gdb) q # quit
Quick Reference
Command Effect gcc -ginclude debug symbols in the binary gdbtui ./proglaunch GDB with split source/command UI gdb --args ./prog a bpass arguments to the program, not to GDB rrun (or restart) the program b <line>set a breakpoint at a line or function nnext line — step over function calls sstep — enter function calls ccontinue until next breakpoint print <expr>evaluate and print an expression once disp <expr>auto-print an expression after every step btshow the full call stack p/x <expr>print value in hexadecimal watch <var>pause when a variable changes refresh/refredraw the TUI when it glitches qquit GDB Created on July 2026 -
C — Function Pointers
A function pointer stores the address of a function in memory and lets you call it indirectly. This enables callbacks, generic utilities, and runtime behaviour selection.
Syntax
The declaration mirrors a normal pointer but wraps the name in parentheses and includes the return type and parameter types:
int (*op)(int, int); // pointer to a function: takes two ints, returns intAssigning and calling:
int add(int a, int b) { return (a + b); }
int sub(int a, int b) { return (a - b); }

int (*op)(int, int);

op = &add;
printf("%d\n", op(3, 4));   // 7

op = ⊂
printf("%d\n", op(3, 4));   // -1
The
&is optional — a function name alone already decays to its address — but writing it makes the intent explicit.Passing a Function Pointer to a Function
This is the callback pattern: a function receives another function as a parameter and calls it internally.
int apply(int a, int b, int (*f)(int, int))
{
    return (f(a, b));
}

printf("%d\n", apply(10, 3, &add));   // 13
printf("%d\n", apply(10, 3, &sub));   // 7
void * — Generic Callbacks
When the data type is not known at compile time, use
void *as the parameter type. The caller casts to the right type inside the callback.void apply(void *data, void (*f)(void *)) { f(data); }Example callback printing an
int:void print_int(void *data) { printf("%d\n", *(int *)data); } int n = 42; apply(&n, print_int); // 42Example callback printing a
char *:void print_str(void *data) { printf("%s\n", (char *)data); } apply("hello", print_str); // helloThis pattern is used extensively in linked-list functions like
ft_lstiterandft_lstmap.typedef for Readability
Long function pointer types can be aliased with
typedef:typedef void (*t_callback)(void *); void run(void *data, t_callback f) { f(data); }Dispatch Tables
An array of function pointers acts as a lookup table — a clean alternative to long
if/elseorswitchchains:int add(int a, int b) { return (a + b); } int sub(int a, int b) { return (a - b); } int mul(int a, int b) { return (a * b); } int (*ops[3])(int, int) = {add, sub, mul}; int result = ops[1](10, 4); // calls sub → 6Indexed by an enum or integer, dispatch tables make it easy to extend behaviour without touching existing logic.
Quick Reference
Syntax Meaning int (*f)(int, int)pointer to function returning int, taking two ints f = &addassign address of function addtoff(a, b)call the function through the pointer void (*f)(void *)generic callback — takes any pointer, returns nothing *(int *)datacast void *back toint *then dereferencetypedef void (*t_cb)(void *)alias a function pointer type Created on July 2026 -
C — Linked Lists
A linked list is a chain of nodes where each node holds a value and a pointer to the next node. Unlike arrays, nodes are scattered in heap memory — the links are what connect them.
[value | next] → [value | next] → [value | next] → NULL
   head                                               tail
The Node Struct
typedef struct s_node
{
    int             value;
    struct s_node   *next;
}   t_node;
The
nextpointer usesstruct s_node *(nott_node *) because the typedef is not yet complete at that point in the declaration.For a generic list (storing any type), use
void *for the content:typedef struct s_list { void *content; struct s_list *next; } t_list;Creating a Node
Always allocate on the heap — stack-allocated nodes are destroyed when the function returns:
t_node  *new_node(int value)
{
    t_node *node;

    node = malloc(sizeof(t_node));
    if (!node)
        return (NULL);
    node->value = value;
    node->next  = NULL;
    return (node);
}
Always check the return value of
malloc— if it returnsNULL, allocation failed.Building a List
Add to the Front
Prepending is O(1) — no traversal needed:
void push_front(t_node **head, int value) { t_node *node; node = new_node(value); if (!node) return ; node->next = *head; *head = node; }headis a double pointer so the function can update the caller’s pointer.t_node *list = NULL; push_front(&list, 3); // [3] push_front(&list, 2); // [2] → [3] push_front(&list, 1); // [1] → [2] → [3]Add to the Back
Appending requires traversing to the last node — O(n):
void    push_back(t_node **head, int value)
{
    t_node *node;
    t_node *current;

    node = new_node(value);
    if (!node)
        return ;
    if (!*head)
    {
        *head = node;
        return ;
    }
    current = *head;
    while (current->next)
        current = current->next;
    current->next = node;
}
Traversing a List
Walk from
headtoNULL, processing each node:void print_list(t_node *head) { t_node *current; current = head; while (current) { printf("%d\n", current->value); current = current->next; } }Never modify
headdirectly while traversing — use a separatecurrentpointer.Searching
Return the first node that matches a value, or
NULLif not found:t_node *find(t_node *head, int target) { while (head) { if (head->value == target) return (head); head = head->next; } return (NULL); }List Size
int ft_lstsize(t_node *head)
{
    int count;

    count = 0;
    while (head)
    {
        count++;
        head = head->next;
    }
    return (count);
}
Last Node
t_node  *ft_lstlast(t_node *head)
{
    if (!head)
        return (NULL);
    while (head->next)
        head = head->next;
    return (head);
}
Deleting a Node
To remove a node from the middle, re-link the previous node’s
nextto skip it:void delete_node(t_node **head, int target) { t_node *current; t_node *prev; current = *head; prev = NULL; while (current) { if (current->value == target) { if (prev) prev->next = current->next; else *head = current->next; // deleting the head free(current); return ; } prev = current; current = current->next; } }Freeing the Entire List
Walk the list and free each node. Advance the pointer before freeing the current node:
void    free_list(t_node **head)
{
    t_node *current;
    t_node *next;

    current = *head;
    while (current)
    {
        next = current->next;   // save next before freeing
        free(current);
        current = next;
    }
    *head = NULL;   // prevent dangling pointer
}
Never call
current = current->nextafterfree(current)— the memory is invalid.Applying a Function to Every Node
Iterate over the list and call a function on each node’s content:
void    ft_lstiter(t_list *lst, void (*f)(void *))
{
    while (lst)
    {
        f(lst->content);
        lst = lst->next;
    }
}
This is the
void *function pointer pattern —fcan be any function that takes avoid *.Doubly Linked Lists
A doubly linked list adds a
prevpointer so you can traverse in both directions:typedef struct s_dnode { int value; struct s_dnode *next; struct s_dnode *prev; } t_dnode;Insertion and deletion are more complex (two pointers to update instead of one), but moving backwards or deleting a node given only its pointer becomes O(1).
Linked List vs Array
Array Linked List Access by index O(1) O(n) Insert at front O(n) O(1) Insert at back O(1) amortised O(n) singly / O(1) with tail pointer Insert in middle O(n) O(n) to find, O(1) to link Memory contiguous — cache friendly scattered — pointer overhead per node Resize realloc needed just add a node Use a linked list when you insert or remove frequently at the front, or when the size changes unpredictably. Use an array when you need fast indexed access.
Quick Reference
Operation Key point Create node malloc(sizeof(t_node)), check for NULL, setnext = NULLPush front O(1) — new node’s next= old head, update headPush back O(n) — traverse to last, set last->next= new nodeTraverse use a currentpointer, never moveheadDelete node re-link prev->nextto skip the node, thenfreeFree list save nextbeforefree, sethead = NULLafterDouble pointer **headrequired when a function must update the caller’s head Created on July 2026 -
C — Structs
A
structgroups variables of different types under one name — useful for representing real-world objects like a point, a player, or a node in a list.
Declaring a Struct
struct s_point
{
    int x;
    int y;
};
To use it you must write
struct s_pointevery time, which is verbose.typedefsolves this by creating an alias:typedef struct s_point { int x; int y; } t_point; t_point p; p.x = 10; p.y = 20; printf("(%d, %d)\n", p.x, p.y);A common convention is
s_prefix for the struct tag andt_prefix for the typedef name.Accessing Members
Use
.to access a member through a variable, and->through a pointer:t_point p; t_point *ptr = &p; p.x = 5; // direct access ptr->x = 5; // pointer access — equivalent to (*ptr).xStructs as Function Parameters
Passing a struct by value copies the whole thing. Pass a pointer instead to avoid the copy and to allow the function to modify the original:
void    move(t_point *p, int dx, int dy)
{
    p->x += dx;
    p->y += dy;
}

t_point pos = {0, 0};
move(&pos, 3, 5);
printf("(%d, %d)\n", pos.x, pos.y);   // (3, 5)
Nested Structs
Structs can contain other structs:
typedef struct s_rect
{
    t_point top_left;
    t_point bottom_right;
}   t_rect;

t_rect r;
r.top_left.x = 0;
r.bottom_right.x = 100;
Self-Referential Structs — Linked Lists
A struct can hold a pointer to another struct of the same type. This is the foundation of linked lists:
typedef struct s_node
{
    int             value;
    struct s_node   *next;
}   t_node;
Each node points to the next one. The last node’s
nextisNULL.t_node *head = malloc(sizeof(t_node)); head->value = 1; head->next = malloc(sizeof(t_node)); head->next->value = 2; head->next->next = NULL;Traversing the list:
t_node *current = head;
while (current)
{
    printf("%d\n", current->value);
    current = current->next;
}
Structs with malloc
For dynamic allocation, use
sizeofwith the struct type:t_point *p = malloc(sizeof(t_point)); if (!p) return (1); p->x = 10; p->y = 20; free(p);
Quick Reference
Syntax Meaning struct s_foo { ... };declare a struct typedef struct s_foo { ... } t_foo;declare with alias p.xaccess member of a variable ptr->xaccess member through a pointer sizeof(t_foo)size of the struct in bytes struct s_node *nextself-referential pointer (linked list) Created on July 2026 -
C — Makefile
A
Makefileautomates compilation. Instead of retypinggcccommands every time, you runmakeand the build system figures out what needs to be rebuilt.
A Minimal Makefile
NAME    = my_program
CC      = gcc
CFLAGS  = -Wall -Wextra -Werror
SRCS    = main.c utils.c
OBJS    = $(SRCS:.c=.o)

all: $(NAME)

$(NAME): $(OBJS)
	$(CC) $(CFLAGS) $(OBJS) -o $(NAME)

%.o: %.c
	$(CC) $(CFLAGS) -c $< -o $@

clean:
	rm -f $(OBJS)

fclean: clean
	rm -f $(NAME)

re: fclean all

.PHONY: all clean fclean re
How It Works
Variables
NAME = my_program # output binary name CC = gcc # compiler CFLAGS = -Wall -Wextra -Werror # compiler flags SRCS = main.c utils.c # source files OBJS = $(SRCS:.c=.o) # replace .c with .o automatically$(VAR)expands a variable.$(SRCS:.c=.o)is a substitution reference — it producesmain.o utils.ofrommain.c utils.c.Rules
A rule has the form:
target: prerequisites recipe- target — the file to produce (or a phony label like
clean) - prerequisites — files the target depends on; if any are newer, the recipe runs
- recipe — shell commands to run (must be indented with a real tab, not spaces)
Pattern Rule
%.o: %.c $(CC) $(CFLAGS) -c $< -o $@%is a wildcard.$<is the first prerequisite (the.cfile),$@is the target (the.ofile). This single rule compiles every.cinto its matching.o..PHONY
.PHONY: all clean fclean reTells
makethese targets are not real files. Without this, if a file namedcleanexisted,make cleanwould do nothing.Mandatory Rules
Rule Effect make/make allcompile the program make cleanremove .oobject filesmake fcleanremove .ofiles and the binarymake refull rebuild from scratch ( fcleanthenall)Every C project should have all four.
Incremental Compilation
makeonly recompiles files that changed. If you editutils.c, onlyutils.ois rebuilt —main.ois untouched. This saves time on large projects.Common Mistakes
Spaces instead of tabs — the recipe line must start with a tab character. Most editors show them the same but
makewill refuse:Makefile:10: *** missing separator. Stop.Forgetting
fcleanremoves the binary —cleanonly removes.ofiles.fcleanalso removes$(NAME). Both are required.Not listing all source files — if
SRCSis incomplete, some files won’t compile and you’ll get linker errors about undefined symbols.
Quick Reference
Syntax Meaning $(VAR)expand variable $(SRCS:.c=.o)substitution: replace .cwith.o$@the target of the current rule $<the first prerequisite %.o: %.cpattern rule matching any .c→.o.PHONYdeclare targets that are not files -cflagcompile to .owithout linkingCreated on July 2026 - target — the file to produce (or a phony label like
-
C — Header Files
A header file (
.h) declares the interface of your code — function prototypes, types, constants, and macros — so that multiple.cfiles can share them without duplicating declarations.
Why Header Files
In C, you must declare a function before calling it. When a project grows beyond one file, repeating declarations in every
.cis error-prone. A header file centralises them:project/ ├── main.c ├── math_utils.c └── math_utils.hmath_utils.hdeclares whatmath_utils.cprovides.main.cincludes the header and gains access to those declarations without needing to know the implementation.What Goes in a Header
Put in .hKeep in .cFunction prototypes Function bodies typedef/structdefinitionsLocal variables #defineconstants and macrosstatichelpersexternvariable declarationsVariable definitions Never put function bodies or variable definitions in a header — they would be compiled multiple times if the header is included in several files.
A Minimal Header
/* math_utils.h */
#ifndef MATH_UTILS_H
# define MATH_UTILS_H

int add(int a, int b);
int sub(int a, int b);
int clamp(int val, int min, int max);

#endif
The three lines around the content are the include guard — explained below.
Include Guards
If a header is included more than once in the same translation unit (directly or through another header), the compiler would see duplicate declarations and error. An include guard prevents this:
#ifndef MATH_UTILS_H   // if not yet defined...
# define MATH_UTILS_H  // ...define this token...

/* all your declarations */

#endif                 // end of guarded block
On the first inclusion the token is undefined, so the block is processed and the token is defined. On any subsequent inclusion the token already exists, so the entire block is skipped.
The token name is conventionally the filename in uppercase with
.replaced by_.#include— Angle Brackets vs Quotes#include <stdio.h> // system / standard library header #include "my_file.h" // your own header (searched relative to the source file first)Syntax Search path <header.h>system include paths (GCC’s standard library locations) "header.h"current directory first, then system paths Always use quotes for your own headers and angle brackets for standard library ones.
Sharing Types and Constants
Headers are the right place for types and constants that multiple files need:
/* types.h */
#ifndef TYPES_H
# define TYPES_H

# define BUFFER_SIZE 1024
# define MAX_PLAYERS 4

typedef struct s_player
{
    char    name[64];
    int     score;
    int     lives;
}   t_player;

#endif
Any
.cfile that includestypes.hcan uset_player,BUFFER_SIZE, andMAX_PLAYERS.Linking Headers and Sources
The header declares; the source defines. Both must agree on the signature:
/* math_utils.h */
int add(int a, int b);
/* math_utils.c */ #include "math_utils.h" int add(int a, int b) { return (a + b); }/* main.c */ #include <stdio.h> #include "math_utils.h" int main(void) { printf("%d\n", add(3, 4)); // 7 return (0); }Compile all
.cfiles together:gcc -Wall -Wextra -Werror main.c math_utils.c -o my_programOr let the Makefile handle it with a pattern rule.
The
externKeywordTo share a variable across files, declare it
externin the header and define it once in exactly one.cfile:/* globals.h */ extern int g_frame_count;/* globals.c */ #include "globals.h" int g_frame_count = 0; // one definitionAny file that includes
globals.hcan read and writeg_frame_count. Global variables should be used sparingly — prefer passing data through function parameters.Nested Includes
Headers can include other headers. Include guards ensure there is no infinite loop or duplication regardless of the inclusion order.
A common pattern is a single top-level header that bundles everything:
/* my_project.h */
#ifndef MY_PROJECT_H
# define MY_PROJECT_H

# include <stdlib.h>
# include <unistd.h>
# include "types.h"
# include "math_utils.h"

#endif
Then each
.cfile only needs#include "my_project.h".
Quick Reference
Concept Key point .hfiledeclarations only — no function bodies include guard #ifndef/#define/#endifprevents double inclusion<header.h>system library header "header.h"your own header typedefin.hshare a type across multiple files externin.hdeclare a variable defined elsewhere Makefile compile all .cfiles together — header is included automaticallyCreated on July 2026 -
C — Recursion
A recursive function is a function that calls itself. It is an alternative to loops for problems that can be broken into smaller identical sub-problems.
Structure of a Recursive Function
Every recursive function needs two parts:
- Base case — the condition that stops the recursion
- Recursive case — the call that reduces the problem toward the base case
Without a base case the function calls itself forever until the program crashes.
int factorial(int n)
{
    if (n <= 1)                    // base case
        return (1);
    return (n * factorial(n - 1)); // recursive case
}
The Call Stack
Each time a function is called, the OS pushes a stack frame onto the call stack. That frame stores the function’s local variables, parameters, and return address.
When a recursive function calls itself, a new frame is pushed on top of the previous one. They stack up until the base case is reached, then they unwind one by one as each call returns.
factorial(4)
  └─ factorial(3)
       └─ factorial(2)
            └─ factorial(1)  ← base case, returns 1
         returns 2 × 1 = 2
    returns 3 × 2 = 6
  returns 4 × 6 = 24
The call stack has a fixed size. Too many nested calls exhaust it — this is a stack overflow, which causes a segmentation fault.
Practical Examples
Countdown
void countdown(int n)
{
    if (n < 0)
        return ;
    printf("%d\n", n);
    countdown(n - 1);
}
Print String in Reverse
Recursion naturally defers work until the stack unwinds:
void print_reverse(char *str)
{
    if (*str == '\0')
        return ;
    print_reverse(str + 1);
    write(1, str, 1);   // printed on the way back up
}
Sum of an Array
int sum(int *arr, int size)
{
    if (size == 0)
        return (0);
    return (arr[0] + sum(arr + 1, size - 1));
}
Recursion vs Iteration
Recursion Iteration Readability often cleaner for tree/list problems clearer for simple counters Memory uses call stack (risk of overflow) uses a fixed loop variable Performance function call overhead per step generally faster Norminette rule allowed whileonly (forforbidden)Recursion is the natural fit for problems with a recursive structure: trees, linked lists, path-finding, and divide-and-conquer algorithms.
Common Mistakes
Missing base case — infinite recursion, stack overflow:
int bad(int n)
{
    return (n * bad(n - 1));   // never stops
}
Base case never reached — e.g. decrementing when input is already negative:
int bad(int n)
{
    if (n == 0)       // never hit if n starts negative
        return (0);
    return (bad(n - 1));
}
Always verify your base case covers every possible entry value.
Quick Reference
Concept Key point Base case stops the recursion — must always be reachable Recursive case calls itself with a smaller / simpler input Stack frame memory pushed per call — holds locals and return address Stack overflow too many nested calls exhaust the call stack Unwind return values propagate back up through each frame Created on July 2026